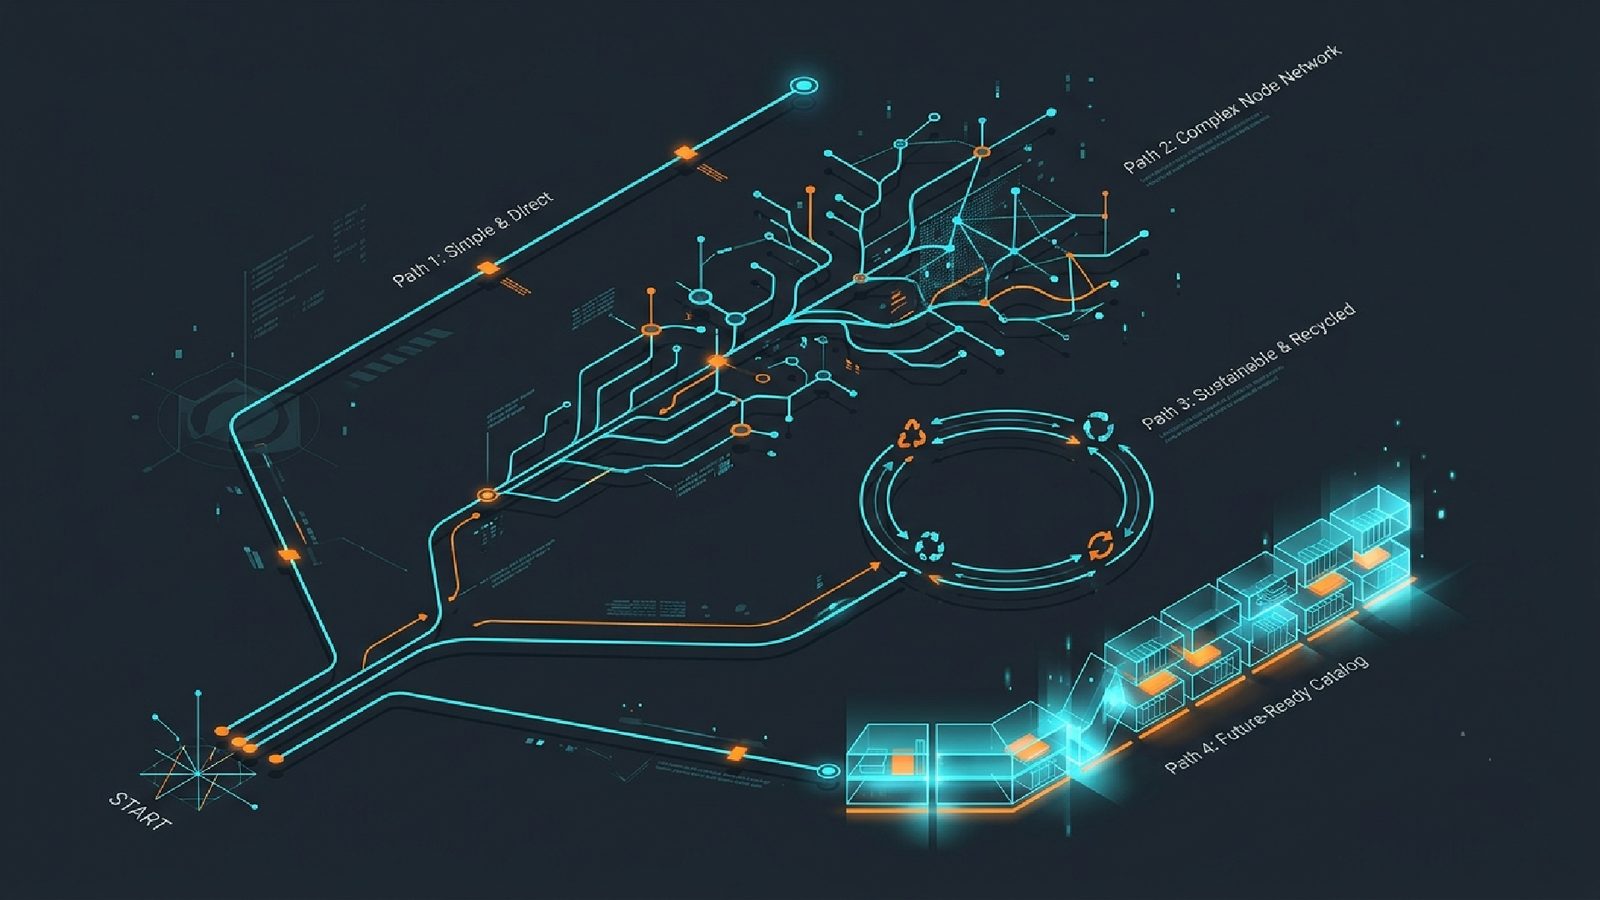
Last post was about the word itself: how “signal” has come to carry an implication of rigor that isn’t always earned, and the three things (scale, correlation, black-box reasoning) that tend to get smuggled in behind it. This post is about what’s actually happening mechanically when someone says an audience was built “from signal.” There isn’t one answer. There are at least four, and they have very different levels of trustworthiness, even though the marketing language around them often sounds identical.
1. Manual composition
This is the oldest and most literal version: a person picks the categories. Interest targeting on the major ad platforms, syndicated intent-topic stacks bought from a data broker, a marketer manually assembling a dozen firmographic and behavioral filters - all of it depends on someone already having a hypothesis about who the buyer is, then translating that hypothesis into filters. The “signal” here is just a label on a pre-existing dropdown menu. It can still work well, but it inherits every limitation of the human hypothesis behind it, and it’s the version most people picture when they hear “old-school targeting.”
2. Seed-and-expand
This is where most of what’s currently marketed as AI-driven audience building actually lives. You give the system a seed - a list of known customers, a CRM upload, a pixel’s worth of purchase events - and a model finds other people who resemble that seed across whatever data it has access to. It’s a real improvement over manual composition in one sense: the machine is doing the resemblance-finding instead of a person guessing at categories. But it inherits a different limitation: it can only ever find more of what you already have. If the seed list is narrow, biased toward whichever channel first acquired those customers, or simply small, the expansion reproduces that same shape at a larger scale. It’s also the version most prone to being a genuine black box: on some platforms - as documented in Meta’s Advantage+ Audience rules - the seed you provide is treated less like an instruction and more like a suggestion the system can override if it thinks it’s found something better, without much visibility into what “better” meant or which traits drove the match.
3. Relabeled personas
Worth calling out on its own, because it looks like the newest category and often isn’t. A lot of what gets pitched as freshly “surfaced” behavioral signal is a direct descendant of segmentation categories that packaged-goods and direct-mail marketers have used for decades: the value shopper, the coupon-driven household, the brand switcher, etc.. These are legitimate, useful categories. But when they show up dressed in signal vocabulary, with no acknowledgment that they’re forty years old, it’s worth asking how much of the “AI” in the pitch is doing new work versus how much is a familiar idea with an unfamiliar name attached.
4. The pre-populated catalog — mostly aspirational, so far
This is the version that would be genuinely new: instead of a marketer supplying a hypothesis (a seed list, a set of categories) and asking the system to act on it, the system proactively mines the available signal space and hands back a shelf of named, ready-to-use audience archetypes nobody had to request.
So, for example, “heavy category buyer, not brand loyal” as a standing segment a marketer could just pull off the shelf. Every architecture above still requires a human to start with a question. This one wouldn’t. As far as I can tell, nobody has shipped this in a form that’s been validated the way it would need to be - with genuine out-of-sample testing against real conversion outcomes, not just correlation within the same dataset that produced the segment. It’s the most interesting direction the category could go, and also the one furthest from actually existing today.
Two things are worth holding onto before the next post. First, these four aren’t mutually exclusive - most real products blend two or three of them, and the marketing language rarely tells you which blend you’re getting. Second, and more important: none of these four architectures, including the most sophisticated one, tells you anything on its own about whether the resulting audience actually converts better than the one it replaced. That’s a separate question, with its own separate problems - which is where we’re headed next.
Next: why the CAC and conversion numbers attached to these architectures deserve more scrutiny than they usually get, and the handful of questions that actually test a claim like “we cut CAC by 65%.”
Start a discussion on this topic in the comments below! Interested to hear how others think about these issues.
View original on LinkedInWant to discuss this further?
Our team thinks about these problems every day. Let's start a conversation.
Book a discovery call